AI helps lawmaker with disability address parliament
Jane Campbell struggles to speak naturally due to spinal muscular atrophy.
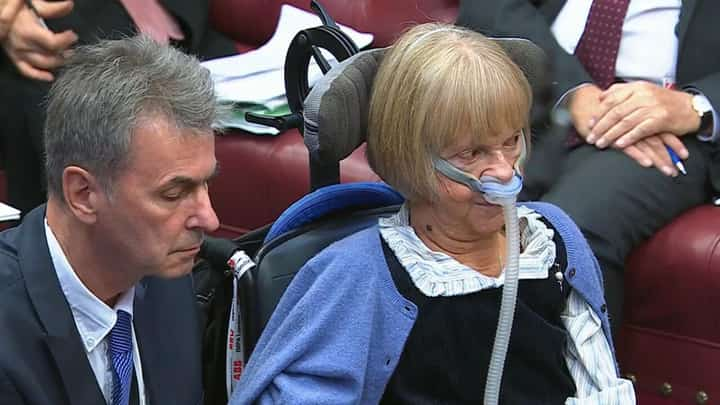
LONDON, United Kingdom (AFP) — A British lawmaker made history on Tuesday by becoming the first person to use an artificial intelligence (AI)-generated voice to deliver a speech in the UK parliament.
Jane Campbell, a peer in the House of Lords upper chamber, struggles to speak naturally due to spinal muscular atrophy, a condition that worsens over time.
During a debate about health on Tuesday, AI software was used to recreate the sound of her voice, as it used to be, to read a speech she wrote herself.
“This my lords is cutting-edge technology and it will enable me to contribute to debates in my own, once-clear voice before it began to deteriorate due to my disability,” the 67-year-old told the chamber.
“I hope your lordships will agree with me that this is an exciting development for the House of Lords, showcasing to the world inclusion in democracy at its best.”
“So my lords, may I introduce you to Baroness Campbell Mark 2,” she added, before her AI-generated voice broadcast her address.
Campbell received permission from the procedure committee — which considers protocol in the Lords, whose origins date back to the 11th century — to use the technology.
In 2012, it had also allowed her to bring her personal assistant into the chamber to read her speeches when required, the House of Lords press office said in a release.
That was a departure from a 1707 ruling which prohibits non-peers from appearing on the floor of the chamber.
‘Authentic’
Campbell approached ElevenLabs, a company that specializes in developing natural-sounding speech, to recreate her voice, the firm’s Gabi Leibowitz told Agence France-Presse (AFP).
The company “worked with her briefly on her voice clone so that we could fine-tune it and make sure that it was exactly how she wanted and felt extremely authentic to her voice before illness,” said Leibowitz, a speech therapist by training.
While 30 seconds of audio can be enough to recreate a voice, the company recommends between 30 minutes and an hour of recording for the best-quality clones.
The technology allows for the insertion of what ElevenLabs calls “emotion tags” — indicators that control the tone of the voice being replicated.
Before the advent of AI, to recreate a voice, someone would have to record almost 400 sentences before they knew they were going to lose their voice, according to Leibowitz.
Even then “you would get a voice that was relatively robotic, didn’t really have any feeling, and was only able to speak that one language,” she told AFP.